


On this page
- Define the funding decision and comparator
- Keep ROI units and costs consistent
- Prepare identity and outcome records
- Verify visitor research and separate measurement
- Compare measurement designs
- Budget complete operating costs
- Report unique units and missing outcomes
- Check whether the case is testable
- Control biases and inappropriate use
- Scope agency reporting separately
- Test sensitivity and break-even
- Review evidence confidence
- Write a conditional executive decision
- Change one operating layer at a time
- Record the investment choice
- Copyable visitor-identification investment record
- Frequently asked visitor-investment questions
Direct answer: Build a visitor-identification business case from unique eligible units, accepted records, actual actions, complete costs and mature outcomes. Compare against a credible baseline; visits, identified people, account associations and opportunities are different units. A match count or attributed pipeline does not establish incremental profit.
Who this is for: CEOs, CFOs, CROs, marketing and RevOps leaders, and agencies that need a visitor-identification-specific investment case. This is not a generic agency ROI report or a client-report template.
BrandWell research pricing is starting at $500/mo. Verify the current TrafficID scope and applicable offers on its product page; keep website identification separate from off-site topic research.
Define the funding decision and comparator
Write the decision in one sentence: “Should we fund this program for the next two quarters at this scope?” Then define what happens without it. The counterfactual might be business-as-usual routing, a holdout group, a delayed regional rollout, or a matched set of accounts. “Before” alone is weak when traffic mix, seasonality, ad spend, or sales capacity changed.
Separate three questions. Match value: how many visits become usable company or person records? Activation value: how many accepted records receive a timely action? Incremental value: how many outcomes occurred because of that action rather than ordinary demand? A vendor can help with the first two; only the measurement design can support the third.
Keep ROI units and costs consistent
Choose one unique decision unit, such as account, before multiplying rates. Define eligibility, match, fit, acceptance and actual action on consistent units and cohorts. Repeat visits and added stakeholders cannot multiply one account opportunity. Apply a separately justified incremental outcome difference, mature win assumption and defined economic contribution. Subtract each incremental program cost once; show excluded costs and uncertainty.
- Eligible unique decision units multiplied by the validated match rate gives matched units. Deduplicate visits and contacts to the chosen account or person unit first.
- Matched units multiplied by the fit rate gives eligible matched units under the frozen definition.
- Eligible matched units multiplied by acceptance gives units approved for the actual action.
- Approved units multiplied by action completion gives units actually acted on.
- Units actually acted on multiplied by a separately justified incremental opportunity-rate difference gives modeled additional opportunities; validate the comparison and exclusions.
- Incremental opportunities × win rate × average gross profit = incremental gross profit.
- Incremental gross profit − software, data, media, labor, implementation, and compliance cost = net benefit.
- Net benefit ÷ total program cost = ROI.
Do not multiply an observed opportunity rate by every identity and call it incremental. Use ranges for match rate, acceptance, lift, win rate, and gross margin. Show the break-even lift: the smallest improvement in opportunity rate needed to cover total cost.
Example with labeled assumptions
An illustrative calculation uses 100,000 eligible unique decision units rather than undeduplicated visits. At 8% matching, 35% fit, 60% acceptance and 70% action, 1,176 units receive an action. An assumed 0.4-percentage-point incremental opportunity difference produces 4.704 expected opportunities. These invented inputs are not benchmarks, observed wins or evidence of causality. Verify consistent account or person units throughout the model before applying actual win rates and contribution.
Prepare identity and outcome records
- Freeze eligibility rules for bots, employees, customers, geographies, consent states, and low-value pages.
- Log raw visits and the versioned identity result, confidence, source, and time.
- Apply ICP, suppression, and account-owner rules before activation.
- Randomize or phase activation where practical. Prevent reps from moving control accounts into treatment.
- Record accepted, rejected, and corrected identities plus the action taken.
- Join opportunity and gross-profit outcomes using predefined windows.
- Review contamination, missing data, small samples, and operational changes before reporting.
Verify visitor research and separate measurement
BrandWell publishes this guide. Evaluate TrafficID visitor research separately from custom CRM joins, client reporting, experiments and managed agency work. This is an investment checklist rather than an independent vendor ranking.
Choose the needed operating scope: observation, identity review, routing, follow-up or measurement. Verify the actual input, output and implementation before committing. A subscription price alone does not establish investment value.
Current TrafficID visitor-research input
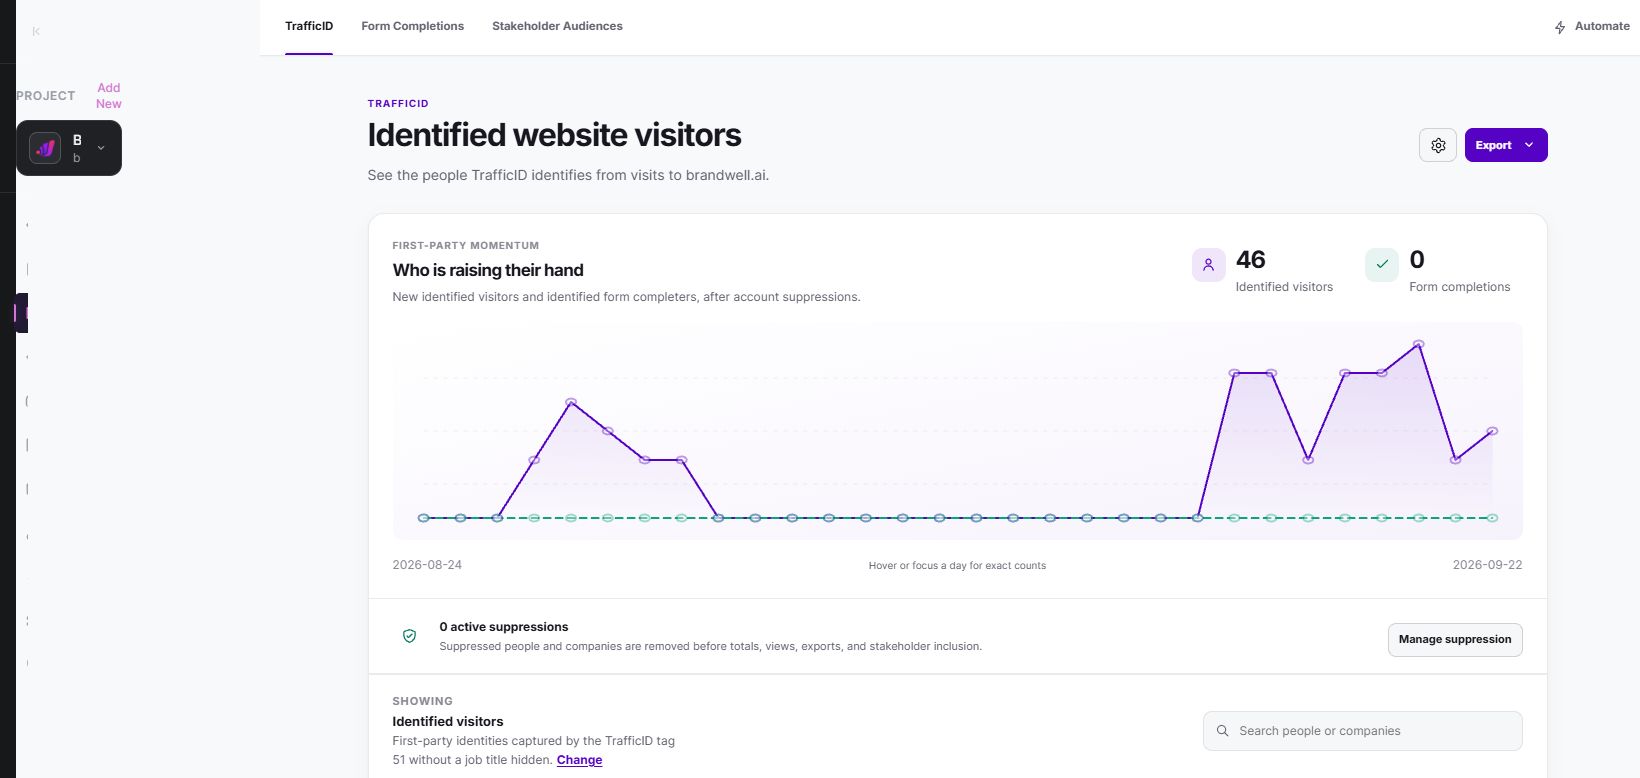
TrafficID is the current BrandWell product for own-site visitor identification. Inspect available visit context and keep observed visitors separate from additional stakeholder contacts. Matching is partial; a visit does not establish readiness or contact permission. Review TrafficID and its demo.
Compare measurement designs
Consider a randomized holdout when you can withhold the activation while still measuring eligible accounts. A phased rollout is practical when randomization is politically difficult. Matched cohorts can help when assignment is not random, but unobserved differences remain. Multi-touch attribution describes recorded interactions; it does not manufacture a counterfactual.
Use observational dashboards for operations and experiments for investment claims. If the sample is too small, report confidence ranges and leading indicators instead of a false point estimate. A low-frequency enterprise sale might require a longer window or account-level outcome rather than person-level conversion.
Budget complete operating costs
Count actual subscription, identification, enrichment, implementation, media, labor, review, ongoing QA and transition costs. Separate cash timing, incurred costs and opportunity cost. Use a current written scope and fees rather than removed vendor price comparisons. Define which costs are already included in gross profit or contribution to avoid subtracting them twice.
Report unique units and missing outcomes
Report eligible visits, matched companies, matched people where allowed, match confidence, ICP-fit rate, accepted records, action latency, action rate, meetings, accepted opportunities, wins, gross profit, complaints, suppressions, and cost. Always display denominators.
Predefine identity and opportunity windows. Deduplicate by account and opportunity. Separate new-logo, expansion, customer, partner, and employee traffic. Show treatment-control balance and contamination. Report both intent-to-treat results and, if useful, action-taken analysis while explaining selection bias.
A CFO-ready page should include base, low, and high scenarios; break-even lift; cash cost; implementation capacity; measurement confidence; downside; and the next review gate. Do not turn a vendor-reported match rate into a revenue promise.
Check whether the case is testable
The model is useful when the site has enough relevant traffic, the ICP is defined, the team can act quickly, outcomes are recorded, and a plausible comparison exists. It is weak when traffic is small, sales cycles exceed the observation window, identity confidence is unknown, or the team ignores routed records.
Do not buy identification solely to increase a dashboard count. If the operating team cannot accept and act on records, fix routing and ownership first. If legal review prohibits the intended use, the theoretical match rate is irrelevant.
Control biases and inappropriate use
Selection bias occurs when the best accounts receive treatment. Attribution bias occurs when already-open opportunities get credited to the signal. Contamination occurs when control accounts receive ads or sales touches. Identity error can assign outcomes to the wrong company or person. Survivorship bias can exclude corrected and suppressed records.
Privacy and trust costs belong in the model. Review notices, consent or lawful basis, vendor contracts, data rights, retention, suppression, cross-border transfer, and channel policies. A research signal is not proof of consent and an identity match is not proof of purchase intent.
Scope agency reporting separately
An agency should report the full funnel, method, assumptions, changes, limitations, and confidence. Renewal should depend on evidence quality and operational value, not a single influenced-pipeline number. Use monthly reports to fix match rules and routing; use quarterly or suitably powered reviews for investment decisions.
Review TrafficID and its actual visitor workflow. Define eligibility, unique units, identity checks, action capacity and outcome windows. Verify current terms before testing. A short operating evaluation cannot establish future incremental profit.
Agent-ready instructions
AIMEE can prepare a review brief through configured connected tools. Keep proposed actions separate from actual approvals and destination acknowledgements. Confirm the implementation and permissions before execution.
Test sensitivity and break-even
A single ROI number hides the variables that matter. Build low, base, and high cases for eligible traffic, match rate, ICP-fit rate, acceptance, action capacity, incremental lift, win rate, gross margin, and cost. Vary one input at a time to show which assumption controls the decision. Test sensitivity to outcome differences, action capacity and identity quality rather than assuming a headline match rate determines value.
Calculate break-even in two directions. First, how much incremental gross profit must the program create to cover total cost? Second, what opportunity-rate lift across activated records would create that gross profit? If the required lift is implausibly high compared with the baseline, change the scope before launch. If break-even is low but the test cannot measure it, extend the window or choose a leading decision metric.
Calculator input definitions
Eligible visits exclude bots, employees, customers when not in scope, unsupported geographies, and pages that do not qualify. Match rate uses records accepted under the same confidence threshold, not every vendor response. ICP fit applies a frozen definition. Acceptance means the operating team agrees the record is usable. Action means a logged, policy-compliant intervention. Incremental lift comes from the comparison design. Gross profit – not revenue – accounts for delivery cost. Program cost includes people and media as well as software.
Version these definitions. If the team lowers the confidence threshold halfway through the period, report the cohorts separately. If traffic spikes because of a campaign, show the mix change. If a large deal dominates results, include an analysis with and without it.
Review evidence confidence
Before approving the business case, ask: Was assignment random or plausibly comparable? Were treatment and control measured under the same identity rules? Did control accounts receive leakage through ads or sales? Were opportunities already open? Did sellers cherry-pick? Are outcome windows long enough? Is sample size large enough to distinguish the proposed lift from noise? Were costs and gross margin verified by finance? Are privacy and complaint costs captured?
Label the answer high, medium, or low confidence and explain why. A medium-confidence positive result can justify another bounded test. It should not be converted into a guaranteed annual return. A null result can still reveal that match quality, speed, or sales adoption is the constraint.
Write a conditional executive decision
Lead with the decision and recommendation. Then show scope, baseline, method, low/base/high economics, break-even, operating capacity, risks, evidence confidence, and the next gate. Put detailed formulas and data definitions in an appendix or downloadable calculator. Keep the narrative short enough that finance can challenge assumptions without reverse-engineering a vendor dashboard.
A useful recommendation is conditional: “Proceed with a two-quarter test for these regions and pages, capped at this cost, if CRM instrumentation and control assignment are complete.” Define stop conditions such as unacceptable identity defects, low action rate, complaints, missing outcome data, or spend above the cap.
Change one operating layer at a time
Improve one layer at a time. Tighten eligible pages, change fit thresholds, adjust routing, train sellers, or shorten action latency. Do not change identity vendor, scoring, audience, script, and measurement simultaneously. Preserve the original control where possible and report each intervention.
The goal is not to maximize identified visitors. It is to find the smallest governed program that creates decision-useful incremental value. Sometimes the correct decision is to keep a lower-cost company-level tool, improve first-party conversion, or stop the program until traffic and operating capacity increase.
Data-readiness gate
Do not begin the paid test until analytics, CRM, identity versions, acceptance reasons, action timestamps, opportunity stages, cost inputs, and control assignment can be exported. Reconcile totals across systems on a small historical sample. Name the analyst who owns exclusions and the executive who can stop the program. A calculator with untraceable inputs is sales collateral, not a finance model.
Record the investment choice
Build the business case backward from the investment decision. Count only usable identities, only actions the team can deliver, and only incremental outcomes supported by a credible comparison. Everything else is diagnostic – not ROI.
TrafficID is own-site visitor research; MarketPulse is separately scoped topic research. Custom client interfaces, branded reports, CRM joins and managed agency services require separately verified implementation, rights and fees. Keep source observations and additional contacts distinct.
Copyable visitor-identification investment record
Decision: [Scope, budget cap and review gate.] Units: [Unique eligible accounts or people; separate visits and stakeholders.] Baseline: [Assignment, comparison, timing and exclusions.] Operations: [Validated matches, accepted actions and capacity.] Economics: [Mature outcomes, defined contribution, costs and cash timing.] Unknowns: [Missing feedback, contamination and untested assumptions.] Choice: [Continue, repair or stop; owner and next test.]
Plan evaluation before interpreting results
HM Treasury’s Magenta Book supports planning evaluation early. An attribution dashboard alone is not a causal evaluation.
Deduplicate visits before valuing opportunities
A fictional site records 1,000 visits, 100 identifiable people and 60 represented accounts. Forty accounts meet the actual eligibility policy and 30 receive an approved action. Five added stakeholders at one company are not five new visitors. A single account opportunity remains one outcome despite repeat visits and several contacts.
Show break-even as an assumption
A fictional 1,000-account eligible cohort has 500 treatment and 500 control accounts. Forty treatment accounts and 30 control accounts have mature qualified outcomes: 8% versus 6%, a two-percentage-point difference, or ten additional outcomes on the 500-account treatment scope. With an assumed 20% win rate and $5,000 contribution per win, the model yields $10,000 expected contribution. Against $8,000 incremental program cost, modeled net benefit is $2,000 and ROI is 25%. These invented inputs are not realized wins or proof of causality; validate assignment, contamination, uncertainty, actual contribution and maturity.
On those assumptions, break-even outcome difference is $8,000 divided by (500 accounts multiplied by 20% win rate multiplied by $5,000 contribution), or 1.6 percentage points. Do not divide by all 1,000 accounts when the modeled expense and activation scope concern only the 500 treatment accounts.
Avoid subtracting the same cost twice
A fictional finance model uses contribution after the specific fulfillment costs. Do not subtract those same fulfillment costs again from that contribution. Keep incremental research, implementation and follow-up expenses separate and show exclusions. A gross-profit model and a cash-payback model answer different questions.
Keep unresolved outcome coverage visible
A fictional 30-action cohort has 24 mature feedback records and four qualified opportunities. Feedback coverage is 80%, with six unresolved records. The outcome rate is 16.7% among reported records or 13.3% among all approved actions. Do not treat missing feedback as either proven failure or proven success.
Frequently asked visitor-investment questions
Are visits, people and accounts interchangeable?
No. Choose a consistent unique unit and preserve the other counts.
Are added stakeholders observed visitors?
No. Keep their source and role separate.
Is influenced pipeline incremental profit?
No. Validate the comparison and actual economic contribution.
Does positive modeled ROI prove realized returns?
No. Label assumptions, mature outcomes, costs and uncertainty.
Review own-site visitor research: explore TrafficID and its demo.
Reviewed and updated October 3, 2026.

Written by

